Low-Latency AI Voice Agents: WebRTC, Speech-to-Text, and Pipeline Architecture
Short answer
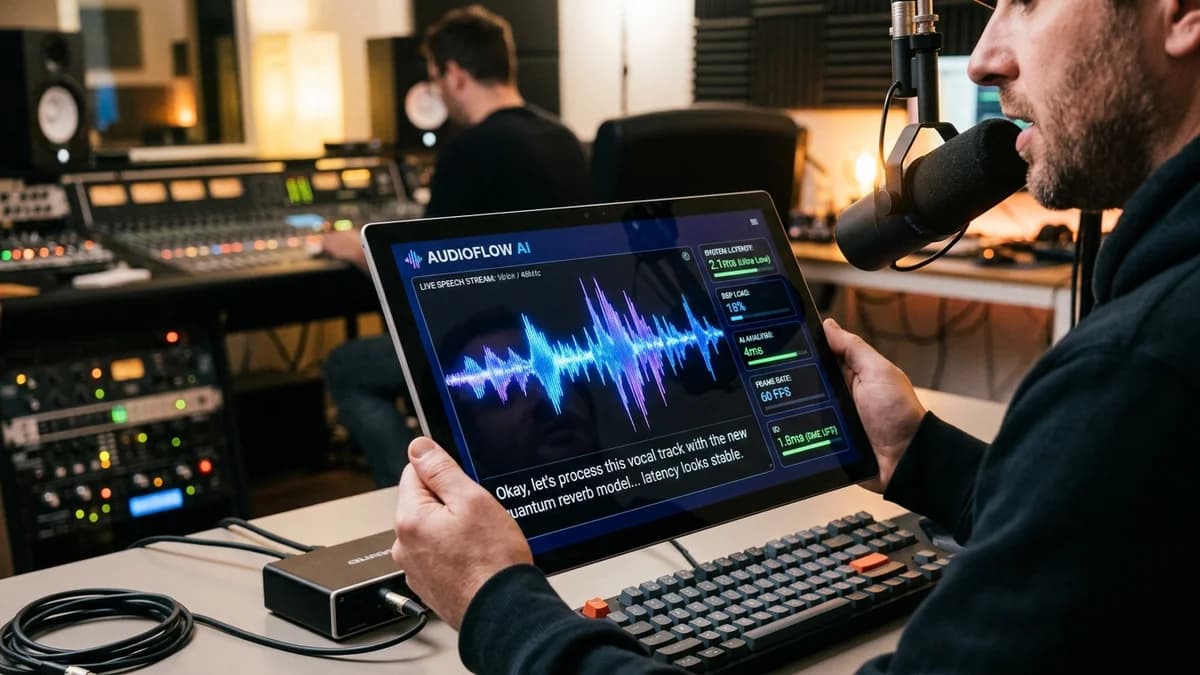
AI voice agents combine audio transport, speech recognition, language-model generation and speech synthesis. Streaming stages and interruption handling can reduce perceived delay, but end-to-end latency depends on networks, model providers and retrieval. Set a latency budget, measure realistic calls and test interruptions, accents and background noise before making a conversational-quality claim.
Software discussed: Dino Business OS · Try the live demo
Human conversation relies on immediate feedback loops; long conversational gaps can feel awkward. Achieving natural speech interactions with artificial intelligence requires aggressive optimization across every link of the audio ingestion, reasoning, and synthesis pipeline.
The Four Stages of Real-Time Voice Pipelines
A production-grade voice agent orchestrates four asynchronous processing stages over bidirectional media streams:
Each stage must stream rather than complete. Transcription emits partial text while the caller is still speaking, generation starts on that partial input, and synthesis begins speaking the first clause before the last one is written. Treating the four stages as a sequence of finished steps produces a pipeline that is correct and unusable, because the pauses land where a human would have answered.
- Full-Duplex Audio Transport: Low-overhead UDP media streaming via WebRTC or binary WebSockets to eliminate HTTP handshake overheads.
- Streaming Speech-to-Text (STT): Chunked acoustic models (e.g., Deepgram Nova-2 or streaming Whisper) returning partial transcripts; benchmark delay on representative audio.
- High-Throughput LLM Inference: High-speed inference hardware or accelerated model endpoints generating first response tokens; measure provider and network latency.
- Chunked Text-to-Speech (TTS): Synthesizing audio buffer streams sentence-by-sentence rather than waiting for full paragraph completion.
- Voice Activity Detection (VAD) & Barge-In: Instantly cutting off synthesized bot playback when the user starts speaking, enabling natural conversational interruptions.
Voice Agent Architecture vs Traditional Chatbot Pipelines
| System Dimension | Real-Time AI Voice Agent | Standard Text-Based Chatbot |
|---|---|---|
| Transport Layer | WebRTC / Binary WebSocket audio stream | Stateless HTTP REST / Server-Sent Events (SSE) |
| Target Latency | Sub-500ms total conversational turn delay | 1,500ms to 3,000ms response generation acceptable |
| Barge-In Handling | Acoustic VAD cancels outgoing audio buffer | Not applicable; user waits for text stream completion |
| Compute Infrastructure | Requires specialized audio streaming worker nodes | Standard cloud container or serverless function |
| Use Cases | Inbound phone customer service, drive-thru, reception | Website knowledge bases, document search, text FAQ |
Latency budgets are what separate the two. A text chat tolerates two seconds of thinking; a phone call does not, because long silence can be mistaken for a dropped line and the caller starts talking over the agent. That budget has to cover transcription, retrieval, generation and speech synthesis together, which is why voice pipelines stream every stage instead of waiting for each to complete.
Explore our AI Agent Development Services and review our RAG Chatbot Engineering capabilities for enterprise integration.
Handling Speech Interruptions with Voice Activity Detection
In natural dialogues, speakers frequently interject or ask clarifying questions mid-sentence. When client-side VAD detects speech during audio playback, the client immediately drops the incoming audio buffer and sends a cancellation signal to the server. The server halts active LLM token generation and restarts the listening state.
Barge-in handling also needs a rollback rule. When a caller interrupts mid-sentence, the agent must stop speaking, discard the unspoken remainder, and keep only what the caller actually heard in the conversation history — otherwise the transcript records an answer the caller never received and the next turn contradicts itself. Getting this wrong is the most common reason a demo that sounds fluent falls apart in production.
Frequently Asked Questions
Deploying Conversational Voice Intelligence
Automate repetitive customer phone calls and voice appointments with low-latency conversational agents. Contact TechDino to architect a custom real-time voice pipeline for your enterprise.
If you need this built against your own data rather than a generic script, TechDino's AI agent development service covers the pipeline described here, and Dino Business OS already ships voice-to-text chat against company records.
Frequently Asked Questions
Can real-time voice agents connect to traditional telephone networks (PSTN)?
Yes. By bridging WebRTC media streams with SIP trunks from providers like Twilio or Telnyx, voice agents handle standard inbound and outbound phone calls.
How are background background noise and accents handled?
Modern acoustic STT models include built-in noise suppression filters and multi-dialect training corpuses that reliably transcribe accented speech.
Can the voice agent query private databases during a call?
Yes. Function-calling tools enable the agent to query database records, verify account numbers, or book calendar slots during live conversations.
Is speech data stored or used for external model training?
No. When deployed on private client infrastructure, transient audio streams are processed in memory and discarded following privacy compliance guidelines.
The software in this article
Dino Business OS
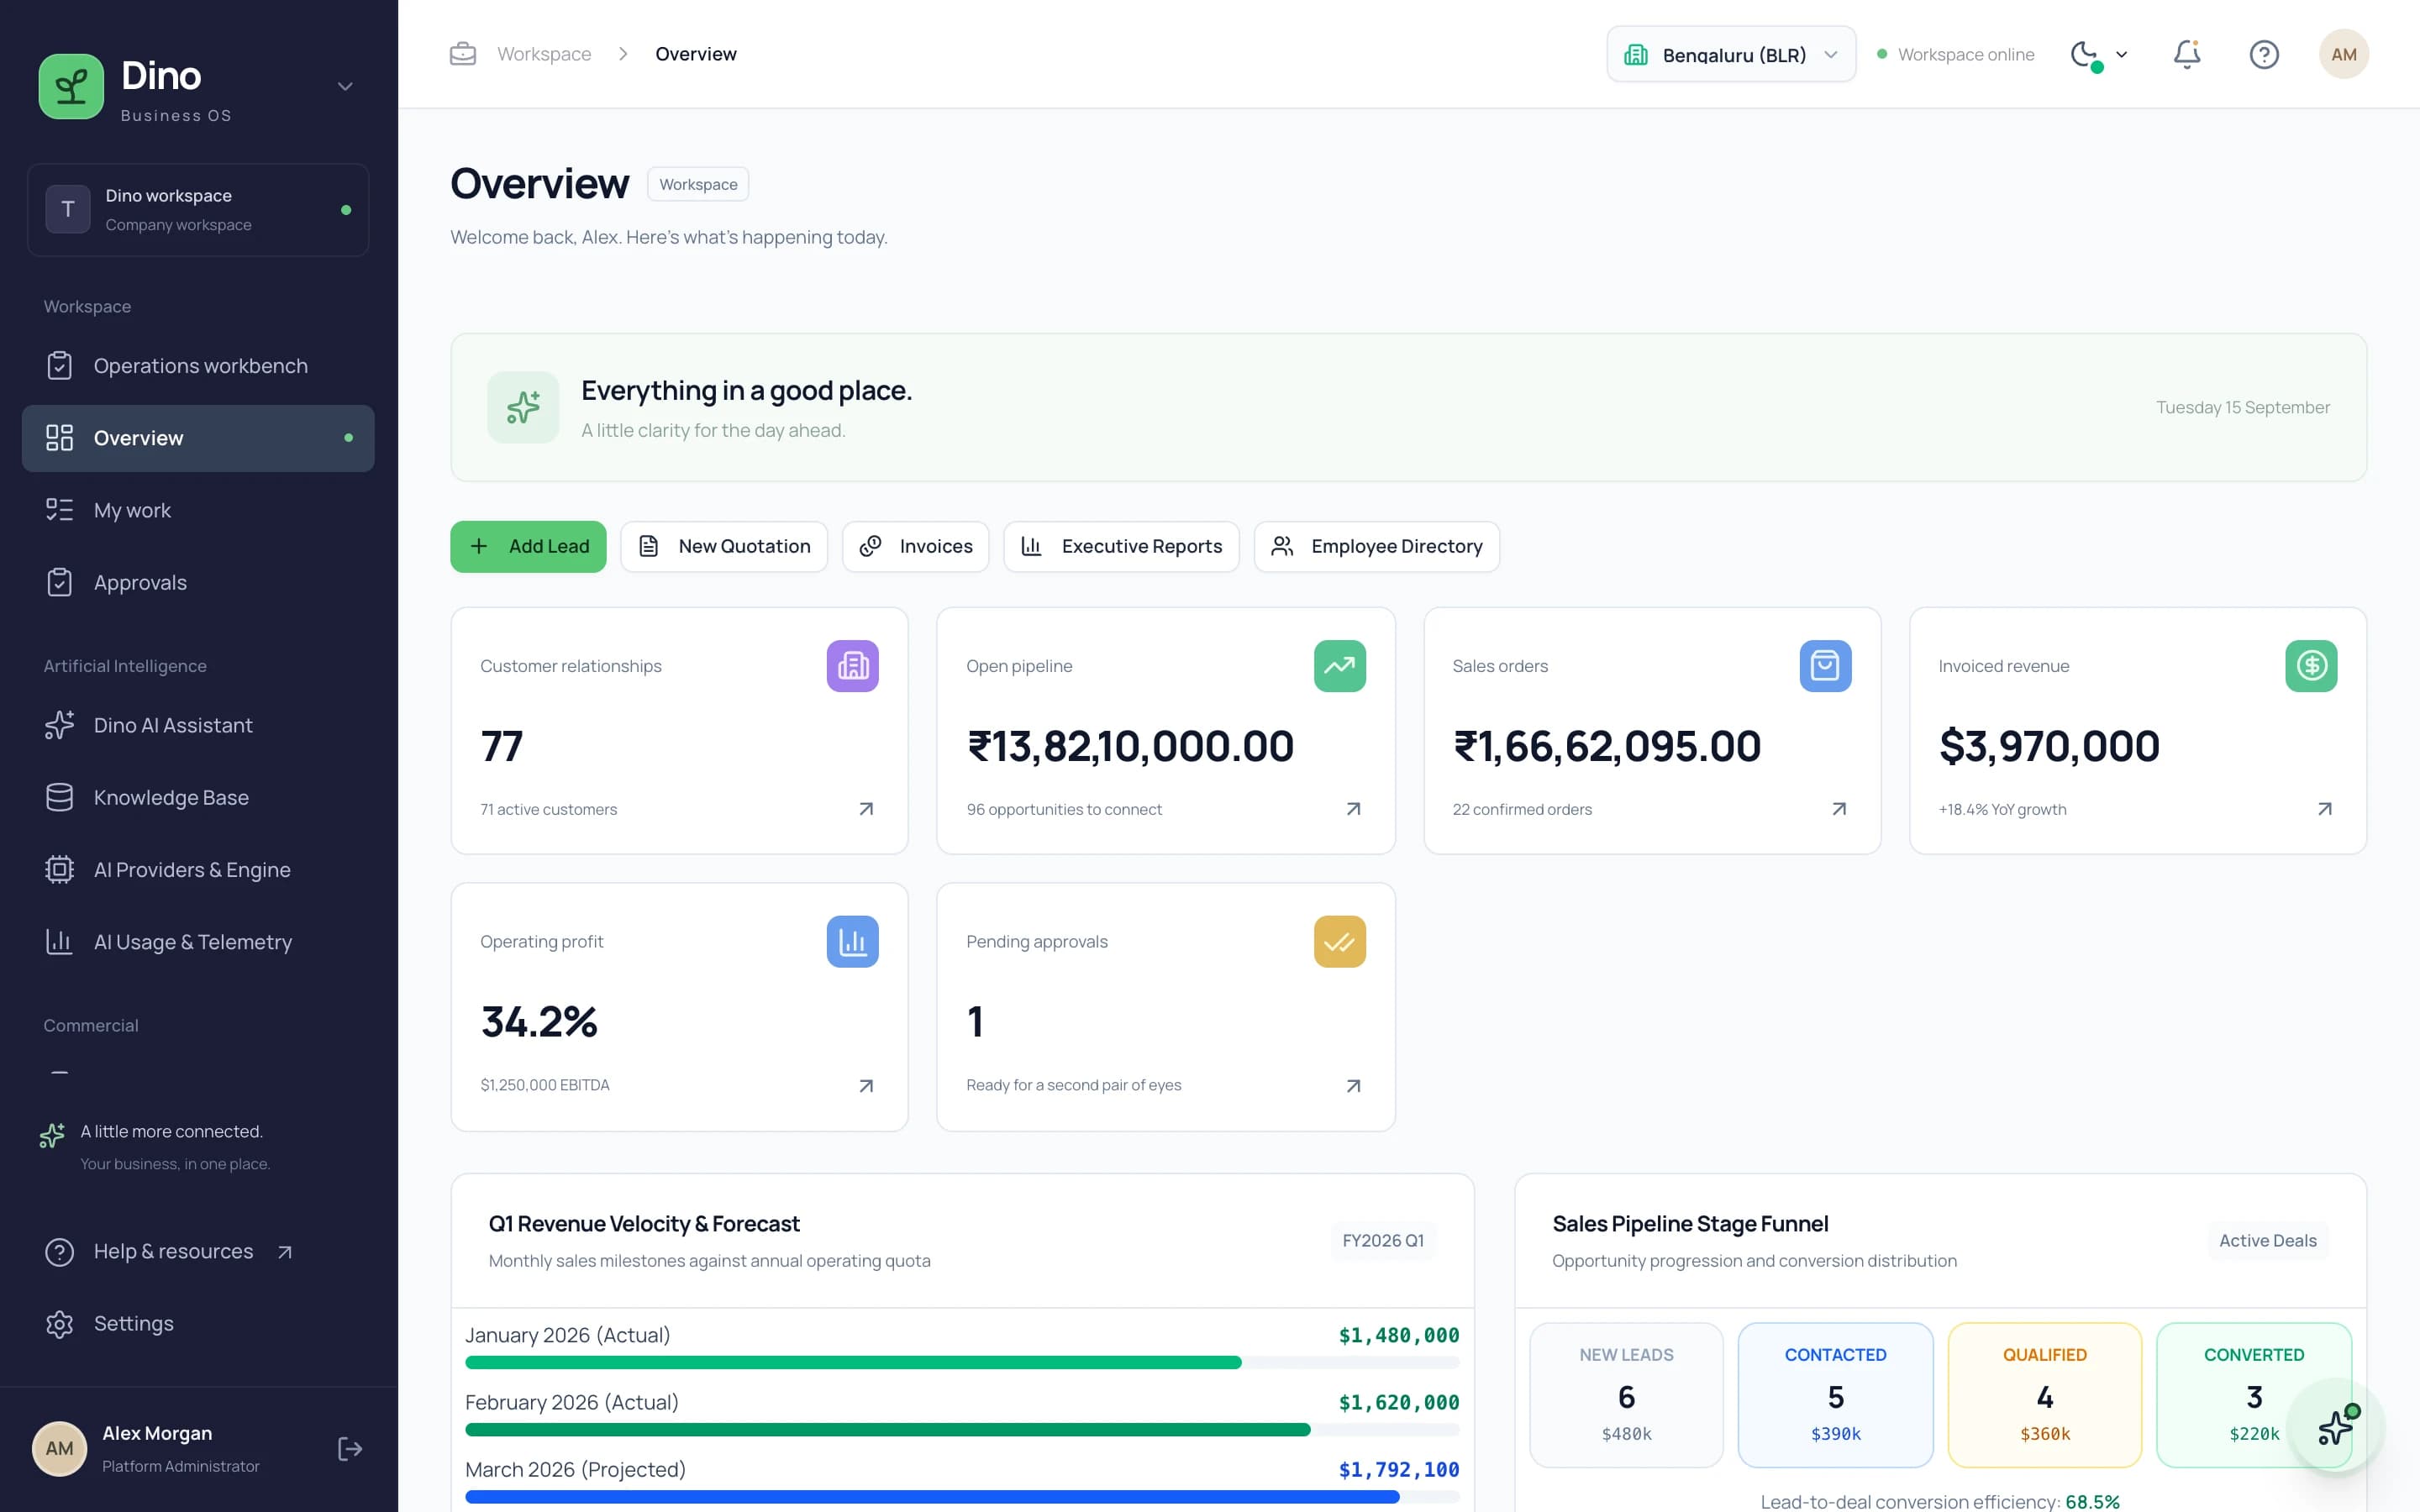
Dino Business OS is AI-powered business operations software that connects CRM, sales, procurement, inventory, projects, HR, payroll, service, assets, documents and finance in one permission-controlled workspace with a built-in LangGraph multi-agent AI assistant.
Explore Next
- Learn about our AI agent development services
Want Dino Business OS Under Your Brand?
Rebrand Dino Business OS with your logo and domain, or have it customized for your workflow. All quotes are customized and private.
Related Articles
Autonomous AI Agents vs Deterministic Workflows: An Engineering Decision Matrix
A practical engineering guide to deciding when to implement autonomous LLM agents versus deterministic state machines for business automation.
Deploying Enterprise RAG on Private Business Documents: Architecture, Vector Databases, and Guardrails
A technical blueprint for deploying enterprise Retrieval-Augmented Generation on private internal documents with pgvector, hybrid search, and hallucination guardrails.